When I became a CIA operations officer, I wasn’t thinking about data pipelines.
I was thinking about people, information, and the mission. About understanding what was happening and getting the right information to the people who needed it.
But somewhere behind every useful piece of intelligence was a less glamorous reality: someone had to get the information collected, processed, connected, and delivered.
Nobody puts that part in the movie.
They probably should. Although “We finally resolved the schema mismatch” would be a difficult line to build a trailer around.
The People Behind the Information
In the field, I relied on talented people to help get me good information. I was fortunate to have them.
They needed reliable ways to ingest and prepare data so analysts could connect the dots and mission teams could act. That meant more than getting information quickly. It meant preserving context, understanding where it came from, and having confidence in what it actually told us.
A useful connection buried in an inaccessible system was still buried. Information that arrived after a decision had been made couldn’t inform that decision.
The people behind that work made an enormous difference. Often, their effort was invisible precisely because they made things work.
Like plumbing: when it works, you barely think about it. When it doesn’t, everyone suddenly wants to know who’s responsible, how soon it can be fixed, and whether someone has tried turning something off and back on.
Then I Built a Software Company
When I later built my first company around an open-source identity intelligence platform, I encountered the same challenge from a different direction.
My thinking was straightforward: collect more datasets, feed the platform, and give users more opportunities to identify connections.
That was a good idea... with a rather substantial amount of work hiding inside the word “feed.”
Every dataset needed attention. Names were inconsistent. Fields were missing. Dates came in different formats. Sources described the same things differently. Some records needed cleaning; others needed considerably more persuasion.
Before the platform could deliver useful insight, engineers had to ingest, normalize, map, transform, and connect the data.
Then a source changed, and part of the process started again.
I had assumed we were turning on another faucet. Occasionally, we were opening the wall and discovering that the previous owner had done the plumbing himself.
That preparation was essential. It was also expensive, time-consuming, and dependent on talented people repeatedly solving variations of the same problems.
I kept wondering how much more we could accomplish if those people didn’t have to spend so much time getting the data ready.
Government Has Plenty of Data (and Plenty of Plumbing Problems)
Government systems were built at different times, for different purposes, with different assumptions about how information would be used.
Imagine a building with additions from several decades, each installed by a different contractor, using different pipes. Now ask everyone to get water from the same faucet by Tuesday.
Getting data across those systems takes real work. Moving it into a new environment takes more. Making it usable, repeatable, and traceable adds another layer.
Those challenges have operational consequences.
An analyst waits for a usable dataset. An engineer spends days repairing an integration. A mission team works with an incomplete picture because relevant information hasn’t made it through the process.
I’ve depended on the people solving those problems, both as an operations officer and as a founder. I have tremendous respect for them.
But even the best plumber shouldn’t have to rebuild the kitchen every time you want a glass of water.
That experience left me with a persistent question: How much of this work could we automate so people could spend more time on the problems that actually require their expertise?
That Question Helped Drive Belvedere
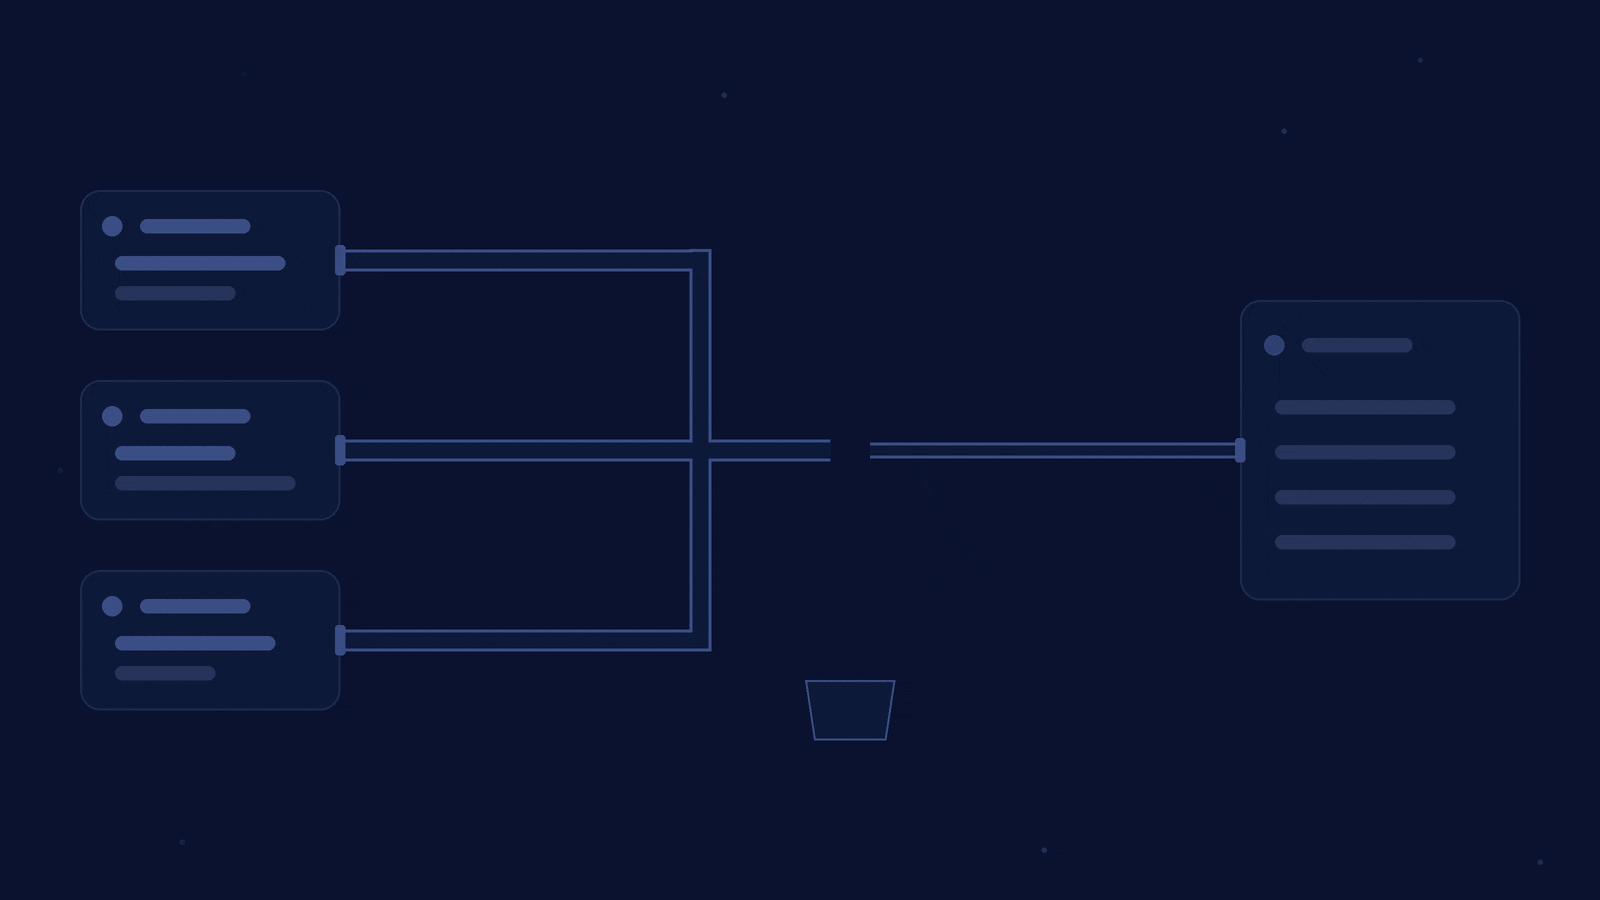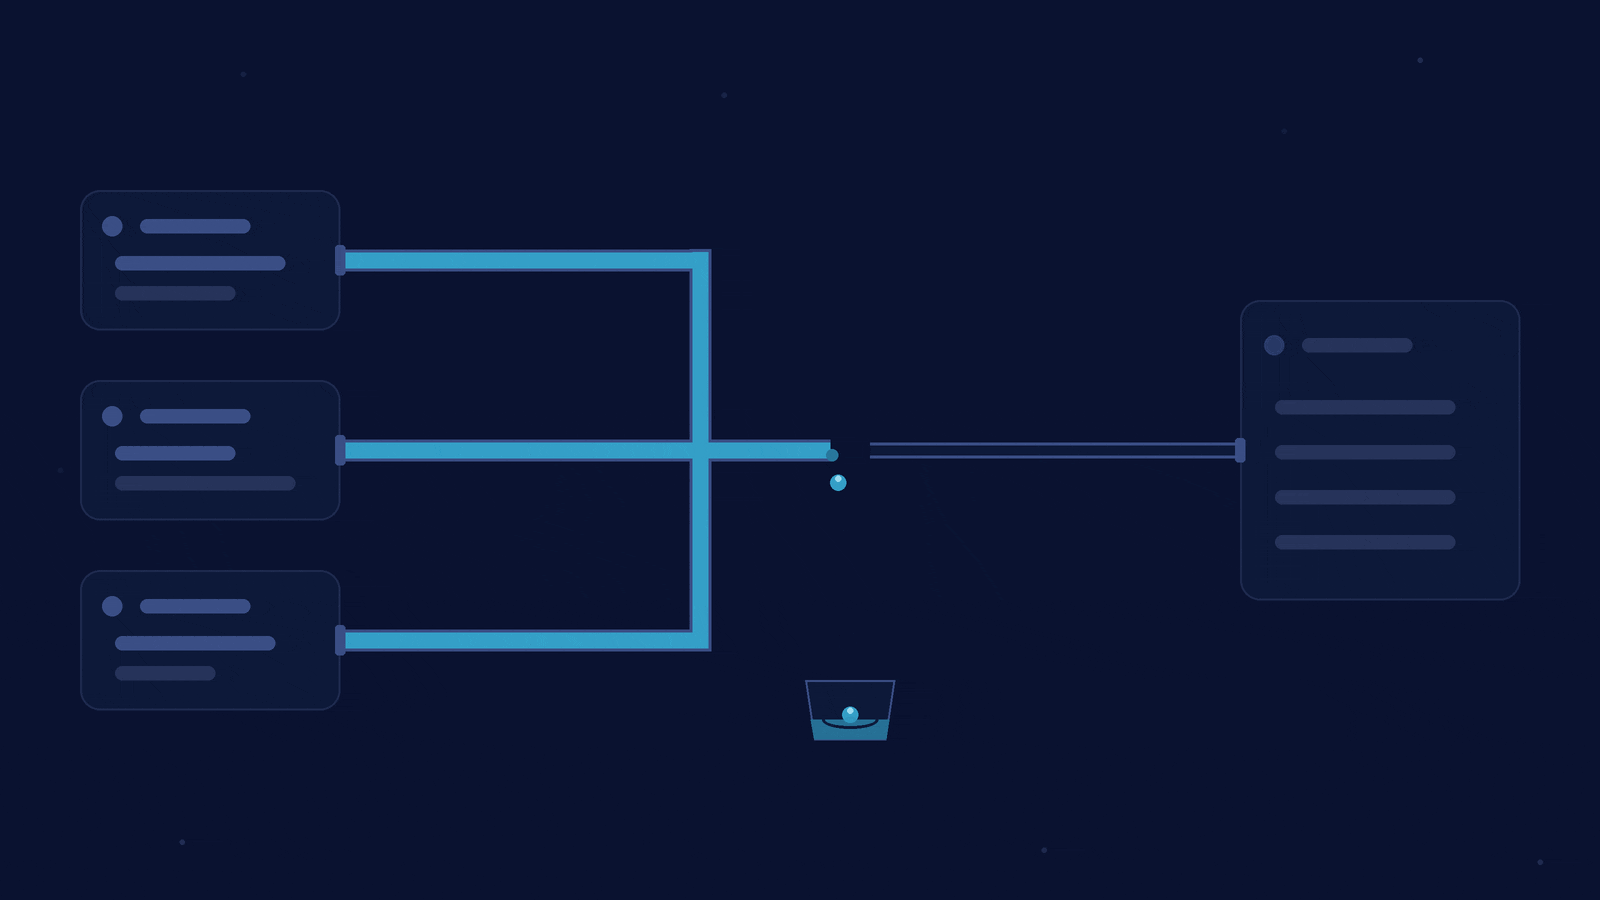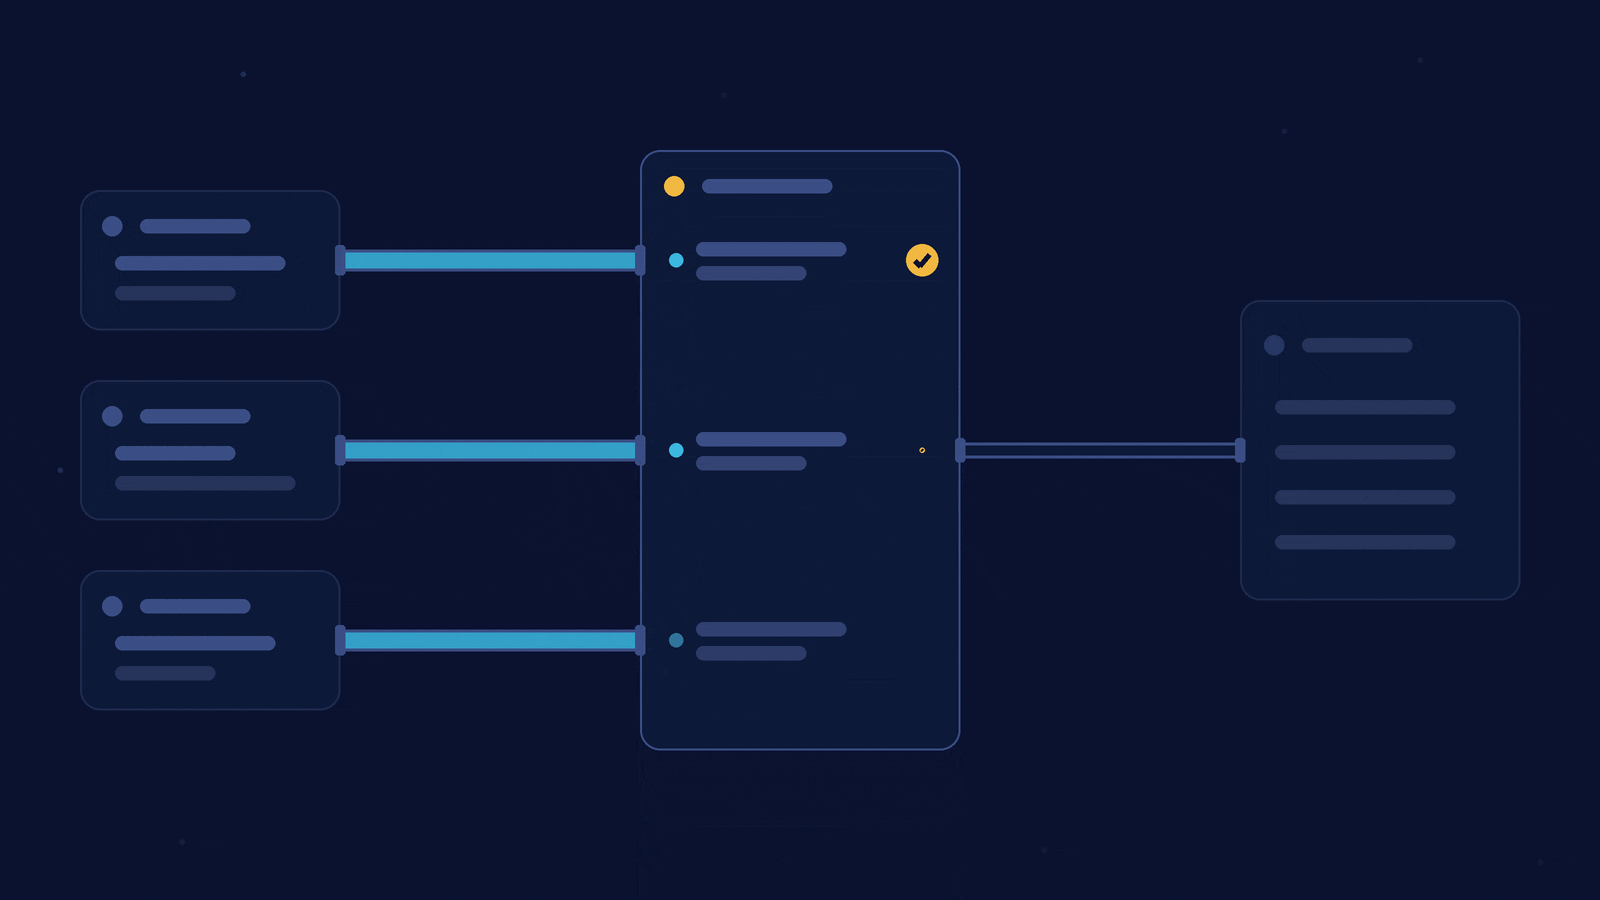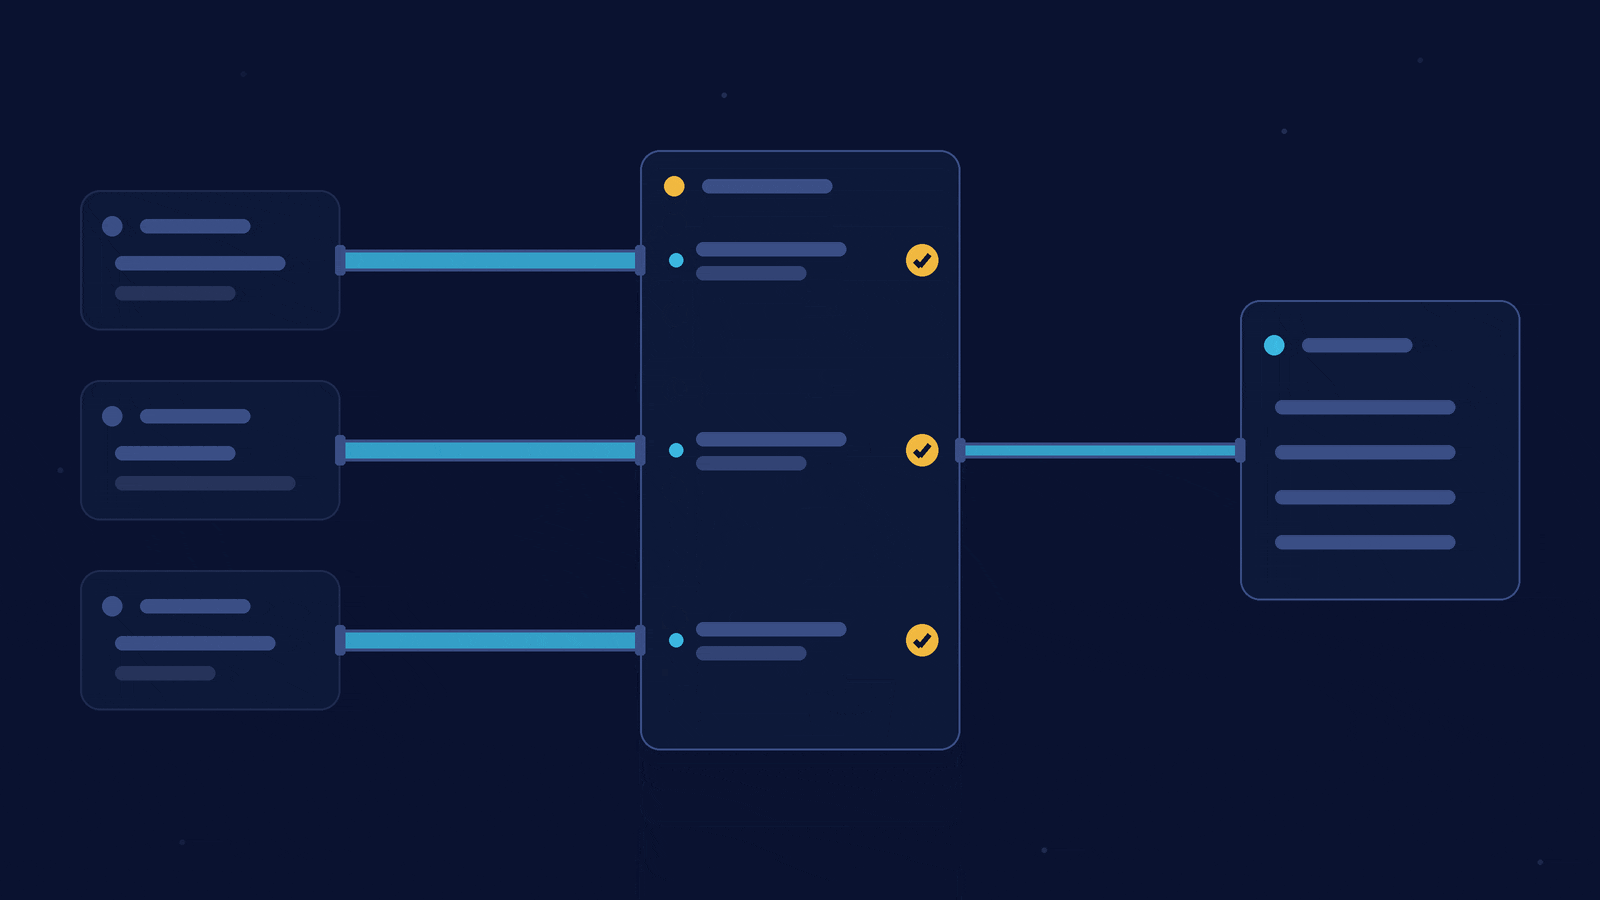
At Clear Fracture, we built Belvedere to automate the data engineering work between having information and being able to use it.
Teams can describe what they need in natural language or use no-code tools to design workflows that ingest, prepare, transform, and integrate data across systems. Belvedere translates those designs into deterministic, repeatable workflows, helps identify and debug problems, and supports migration across vendors and environments.
Versioning, explainability, and audit trails help teams understand what ran, how the data was processed, and what changed. You should be able to trace what came through the pipes without having to call the one person who remembers how they were installed.
For government customers, where the work happens matters too. Belvedere runs in the customer’s environment, including air-gapped environments.
The purpose is practical: reduce the time and effort required to make data usable while giving teams visibility into the process.
There will always be difficult sources, complicated environments, and decisions that require human judgment. Automating the preparation gives people more room to do the work we need them to do.
I Wish I’d Had This Years Ago
I regularly look at what our team has built and think about how much I would have wanted it earlier in my career.
In the field, when timely, well-connected information mattered.
At my first company, when every new dataset brought both opportunity and another engineering bill.
And during all those conversations that began with, “We have the data,” and ended with, “It’s going to take a while.”
I’m deeply grateful to the Clear Fracture team. Their talent and persistence amaze me, but so does their understanding of the purpose behind the work. They know that an integration problem can stand between a person and the information they need to accomplish something important.
Watching them build the capability I wished we’d had years ago has been one of the most rewarding parts of my career.
Data plumbing may never be the glamorous part of national security. But reliable plumbing helps information reach the people who can turn it into understanding and action.
And if we can help our smartest people spend more time connecting the dots and less time standing under a leaking data pipe with a bucket, I’ll happily take the plumbing business.